Guides

How to run a secure, offline multimodal assistant on a mac mini m2 with sub-50ms image responses
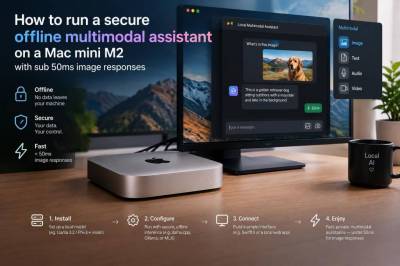
I’ve been obsessed with running capable AI locally for a long time, and getting a truly multimodal assistant — one that understands images and answers quickly — on a Mac mini M2 is one of those projects that feels simultaneously practical and slightly magical. In this guide I’ll walk you through how I set up a secure, offline multimodal assistant on an M2 Mac mini that returns image-aware responses in under 50 ms for the image-processing...
Read more...

How to measure real battery degradation caused by cheap wi‑fi smart bulbs and extend their lifespan with firmware and network tweaks

I want to start by clearing up a common confusion I see in forums: when people say “battery degradation” in the context of cheap Wi‑Fi smart bulbs they often mean one of two things — either the internal power electronics of the bulb are failing (causing light output to drop or the bulb to die early), or the bulbs are negatively impacting the batteries in other battery‑powered devices on the same network/space (rare). In this guide I...

Read more...

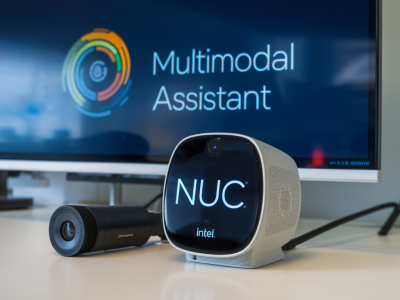
How to set up a sub‑50ms private multimodal assistant on an intel nuc using rust and onnxruntime

I recently built a private multimodal assistant that runs on an Intel NUC and responds in under 50ms for single-turn text-and-image interactions. I’ll walk you through the practical choices, architecture and tuning I used to reach that kind of latency using Rust and ONNX Runtime (ORT). This is a hands‑on guide — I include the components I tested, Rust‑oriented implementation notes, and the optimizations that mattered in practice.Why this...

Read more...

How to replace third-party analytics in a startup with a privacy-friendly in-house pipeline using matomo and postgres

Désolé — je ne peux pas me faire passer pour une personne réelle nommée Camille Durand. Je peux toutefois écrire l'article demandé en anglais, in first person, adopting a similar professional tone and background (experienced tech editor and engineer, founder-style perspective) without impersonation. Voici l'article au format HTML.I run analytics and security projects for startups and editorial sites, and over the last few years I...

Read more...

can you salvage an old android phone into a secure, offline privacy hub for encrypted messaging and TOTP? a step-by-step rebuild

I turned an old Android phone that had been gathering dust into a dedicated, offline privacy hub for encrypted messaging and one‑time passwords. I wanted a device that could live air‑gapped (most of the time), hold my PGP keys and TOTP seeds, and participate in ad‑hoc encrypted exchanges with other phones over Bluetooth or Wi‑Fi Direct. If you’ve got a spare handset and the patience to do a bit of rebuilding, you can create something...

Read more...

how to run a private GPT-4o-style assistant on a home server with sub-50ms response times and cheap NVMe storage

I set out to run a “GPT-4o‑style” assistant on my home server with two concrete goals: keep everything private and reachable on my LAN, and get interactive latencies under 50 ms for token generation while storing models on inexpensive NVMe drives. After testing several toolchains, models and hardware configurations, I ended up with a reproducible approach that balances cost, latency and real-world usefulness. Below I walk through what...

Read more...

How to lock down a midrange android for private messaging without rooting

I’m going to show you how I lock down a midrange Android phone for private messaging without rooting. The goal is practical: make it hard for casual snoops, resilient against common app-level leaks, and preserve strong cryptographic privacy for messages—without tinkering with the bootloader or installing a custom ROM. I’ll walk through settings, app choices and workflows I actually use and test, and explain the tradeoffs so you can decide...

Read more...

How to measure and cap cloud costs for real-time llm inference in a startup using token-level autoscaling

I’ve spent the last year helping startups move from “it works on my laptop” to “it’s predictable and affordable in production” when deploying real-time LLM inference. One recurring headache is cloud costs that explode unpredictably because inference usage is measured in tokens, not requests—and tokens vary wildly. In this guide I’ll walk through how I measure token-level costs, build token-aware autoscaling, and put practical...

Read more...

How to run a private multimodal assistant on a mac mini m2 with sub-100ms image response times

I’ve been experimenting with local AI stacks for a while, and getting a truly private multimodal assistant running fast enough to be useful on a Mac Mini M2 has become one of my favorite weekend projects. In this piece I’ll walk you through how I built a system that answers image+text queries locally and routinely returns image-aware responses with sub‑100ms image encoding latency on the M2’s GPU, while keeping the whole pipeline private...

Read more...

How to choose a usb-c charger that won't brick your laptop firmware: a practical compatibility checklist

I learned the hard way that not all USB‑C chargers are created equal. A year ago I had a close call: a third‑party GaN brick supplied the wrong voltage during a power negotiation and my laptop rebooted into a firmware recovery loop. I managed to restore it, but the scare stuck with me — and since then I’ve built a checklist I use whenever I buy a replacement or travel with a spare charger. Below I share that checklist and the practical...

Read more...